A demonstration produces clean captions from a presenter speaking slowly into a good microphone. Your event has a panel, unfamiliar names, a question from the back of the room, and a speaker who changes direction halfway through a sentence.
The useful question is not whether speech recognition can look impressive. It is whether the tested system helps your audience follow the material under the conditions you can actually provide.
Model names and provider features change. A repeatable evaluation method gives an event team something more durable: evidence about recognition, meaning, timing, and the attendee experience. This guide is an evaluation worksheet, not a ranking of current vendors or a claim that every system reaches the same accuracy.
Define what you are evaluating
Keep the stages distinct. Speech recognition turns audio into text. Translation expresses source-language material in another language. A listener interface displays the result, and an audio option may add another delivery path. An error observed at the end needs investigation before it can be assigned to a particular stage.
First identify the source-language output you will compare with a reference. If you also need translated captions, arrange a separate meaning review with a competent target-language reviewer. A good source transcript is useful input; it does not prove that the translation is correct.
Write the practical purpose: following a lecture, understanding instructions, recognizing speaker changes, or participating in questions. That purpose helps determine which failures matter and what the rehearsal must include.
Select representative samples
Use material you have permission to record and evaluate. Avoid copying sensitive event content into a test service without authorization. A short, well-chosen set of samples is more informative than a long recording that contains only easy speech.
Include the voices, microphones, terminology, and transitions you expect. Label the conditions so you can distinguish a clean prepared passage from an audience question captured differently. Include names, numbers, a negation, an acronym, and an ordinary sentence; do not build a sample consisting entirely of unusual words.
For comparisons, keep the audio and scoring rules consistent. If one run uses a direct feed and another uses a laptop microphone, you changed more than the recognizer. Record that difference instead of attributing the entire result to a model.
Calculate word error rate carefully
Word error rate, or WER, compares recognized words with a reference transcript. It counts substitutions, deletions, and insertions relative to the number of reference words. Microsoft's speech evaluation documentation explains the calculation and the importance of representative test data.
A simplified formula is:
WER = (substitutions + deletions + insertions) ÷ reference words × 100
Decide how punctuation, capitalization, numbers, and contractions are normalized before comparing runs. For a longer sample, use an appropriate alignment tool and inspect the result; visual word-by-word comparison can become misleading after an insertion or deletion.
A checkable fictional example
Reference: Please do not close the door today
There are seven reference words. Compare three independent hypothetical outputs:
| Output | Error | WER for this tiny example |
|---|---|---|
| Please do close the door today | Deletes “not” | 1 ÷ 7, approximately 14.3% |
| Please do not close the door tomorrow | Substitutes “tomorrow” for “today” | 1 ÷ 7, approximately 14.3% |
| Please do not close the blue door today | Inserts “blue” | 1 ÷ 7, approximately 14.3% |
Each output has one word error, but the effect on meaning differs. The first reverses the instruction, the second changes its timing, and the third adds a detail the speaker did not provide. These invented examples teach the calculation; they are not measurements of InterScribe or another service.
Review meaning alongside the score
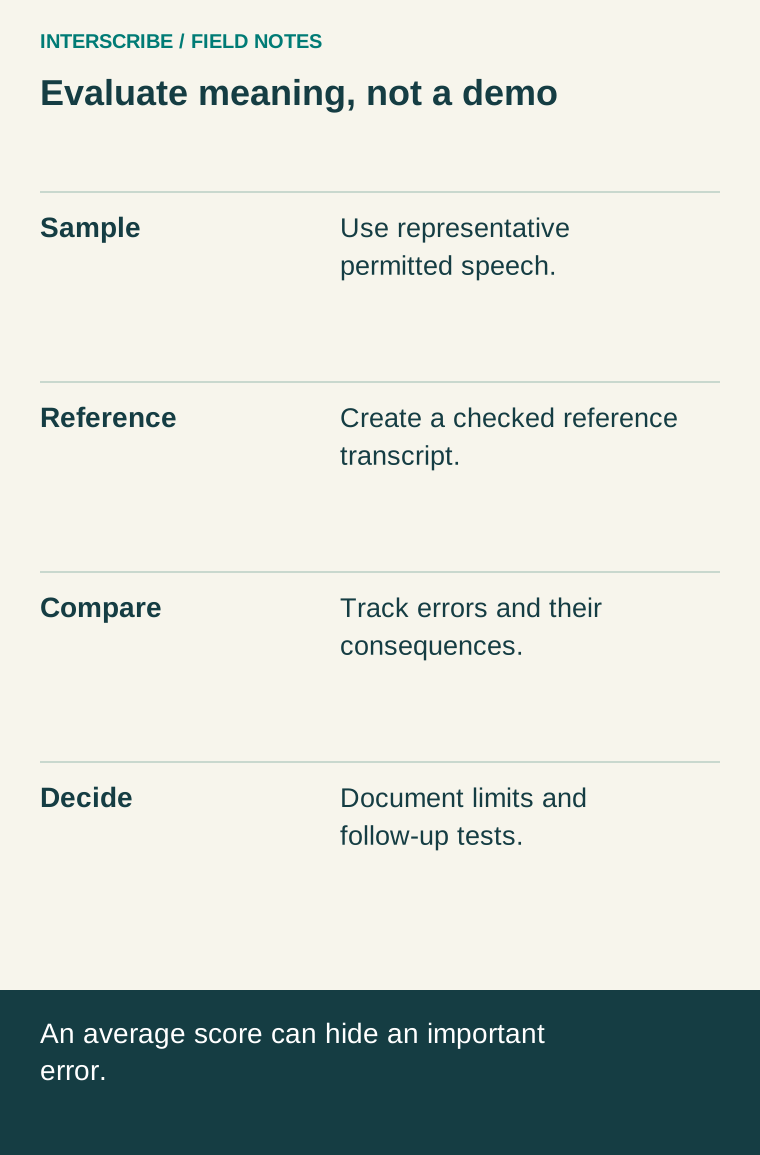
Do not turn a low overall WER into a promise that every consequential detail is right. Read the passages that contain names, quantities, dates, negation, specialized terms, and decisions. Record whether the reader could act on an incorrect meaning.
Also inspect speaker labels and readability where those features are part of the experience. A transcript can contain the right words but attribute them to the wrong person or present them in a way that is difficult to follow.
Use two separate observations: “word mismatch” and “effect on meaning.” Do not invent a universal pass threshold. Agree review criteria with the people responsible for the event and the audience's access needs, including appropriate expertise for consequential content.
Measure a defined delay
Choose a consistent reference point, such as the end of a specified spoken phrase and the appearance of the corresponding readable caption. Record whether you are observing the first partial text or a later revision. Those are different measurements.
Repeat across representative passages and report the variation, not only the best result. Note the source path, network, attendee device, and any video delay. A caption that appears ahead of a delayed broadcast is a different issue from a slow source-to-caption path.
InterScribe's latency and monitoring guide explains the documented delay views. Use the actual measurement's definition; a network round trip is not the same as complete speech-to-caption time. This article does not prescribe a universal seconds-based accuracy or accessibility standard.
Use one evaluation sheet
| Field | What to record |
|---|---|
| Sample and permission | Material, owner, and approved use |
| Conditions | Speaker, microphone, source path, network, and device |
| Reference rules | Checked transcript and normalization choices |
| Recognition result | Error counts, reference length, and reviewed alignment |
| Meaning issues | Exact passage, consequence, and reviewer observation |
| Timing | Start/end definition, partial or revised text, and observed variation |
| Attendee task | Could the tester follow the passage or question exchange? |
| Next action | One relevant change, owner, and focused retest |
For example, if a question microphone never reaches the feed, correct the routing before comparing models. If the sound is clean but a recurring name is wrong, investigate supported terminology preparation and test that passage again. The audio preparation guide and custom vocabulary tutorial address those different tasks.
Keep the result proportional to the test
A rehearsal establishes what happened with the tested material and configuration. It does not prove performance for every accent, language, room, or future event. Record relevant changes and retest when they affect the experience.
Share a short conclusion with the team: what worked, which meaning errors remain, what timing was observed, and what must change before the event. That gives organizers a decision they can act on without hiding uncertainty behind a single accuracy percentage.